

16·
4 days agoHappened to me too, had to reload a couple of times. Not sure if it was intentional, but realistic anyhow xD The only thing missing is random loading times between each step.
Just a lvl 29 guy from Finland. Full-stack web developer, Scrum Master and a team facilitator by trade, but actually more into server-side programming, networking, and sysadmin stuff.
During the summer, I love trekking, camping and other hiking adventures. Also somewhat of an avgeek and a huge Lego fanatic.
A furry or something. Why be yourself when you can be a fluffy raccoon on the internet?
Happened to me too, had to reload a couple of times. Not sure if it was intentional, but realistic anyhow xD The only thing missing is random loading times between each step.
I think Vim is great if you use it everyday and know it inside out. For those of us who don’t, Nano is just easier, not least because it tells you in the UI how to exit it xD
I think it’s written that way because the instructions are meant to work on Windows too. But it still doesn’t make much sense. I think just saying “Install CMake” and letting the agent figure it out for the current environment would be a much better approach.
Also, I think the model they were using was working with outdated data. Why specifically require Java 21 when Java 25 is the latest LTS? And furthermore, why even link to a specific JDK implementation when it surely works with almost any implementation? Probably just makes the agent install the Temurin implementation even if the system already had a working java.
My point being if the author’s idea is to let AI handle the installation to avoid writing environment-specific instructions, it shouldn’t then have these hardcoded assumptions about the environment. So yeah, it seems they (and the AI that wrote it) didn’t really know what they were doing.
Yeah, but I would never let an AI agent run commands on my machine without verifying each command. And at that point I would just rather copy and paste commands by hand, takes about the same time.
If the installation for example required creating some complicated host specific config files, then sure, I could see how that kind of a “runbook” could maybe be useful. But that doesn’t seem to be the case here.

I run Debian on my homelab and manage Ubuntu Servers at work. I haven’t seen any practical differences between the two. Sometimes you might get a bit newer version of something from the Ubuntu repositories than from the Debian ones but not even once has that been an issue and most of stuff I use come from 3rd party repositories anyway.
It works great when you log in as a user like you normally would on a Windows pc. But on a server you want it to run as a service, starting automatically in the background and/or being managed by the failover cluster without requiring a user to log in.
The solution back then was to use netplwiz autologon. Obviously a hack and bad for security, but fine for a homelab. After googling it now, it looks like some other “solutions” are documented in the GitHub issue about this.
Asking out of curiosity: is there a specific reason you’re running Windows on your server? I used to do the same on my home servers because that’s what we used to have at work, and I wanted to learn and test some stuff. But it was a difficult road, to put it mildly. Simple things, like getting Docker autostart on boot seemed almost impossible. At some point I just gave up and switched to Linux.
Never ever add any users to the docker group. Rootless mode is cool tho (albeit with some caveats)
Agreed
I use Caddy and it’s great. ACME is very easy to configure, as is everything else. I haven’t tried running it in a container tho but they have official images published so it should work without issues.
I’ve had a good experience with mailcow. It’s not the most lightweight tho, and spins up quite a few containers.
Obviously I’m not a lawyer but I don’t see what law they could use to shut it down. All it’s doing is accessing publicly available data via a proxy. It’s not like it’s exploiting Instagram somehow.
If they wanna stop it, they can do what Twitter did and start requiring an account to see almost anything. Personally I suspect Meta is slowly going towards that.
Awesome! Got it running and seems to work well. Also I love the CLAUDE.md file you got there in the repo 🐈
I see everyone in this thread recommending a VPN or reverse proxy for accessing Jellyfin from outside the LAN. While I generally agree, I don’t see a realistic risk in exposing Jellyfin directly to the internet. It supports HTTPS and certificates nowadays, so there’s no need for outside SSL termination anymore. (See Edit 2)
In my setup, which I’ve been running for some time, I’ve port-forwarded only Jellyfin’s HTTPS port to eliminate the possibility of someone ending up on pure HTTP and sending credentials unencrypted. I’ve also changed the Jellyfin’s default port to a non-standard one to avoid basic port-scanning bots spamming login attempts. I fully understand that this falls into the security through obscurity category, but no harm in it either.
Anyone wanna yell at me for being an idiot and doing everything wrong? I’m genuinely curious, as the sentiment online seems to be that at least a reverse proxy is almost mandatory for this kind of setup, and I’m not entirely sure why.
Edit: Thank you everyone for your responses. While I don’t agree with everything, the new insight is appreciated.
Edit 2: I’ve been informed that infact the support for HTTPS will be removed in a future version. From v10.11 release notes:
Deprecation Notice: Jellyfin’s internal handling of TLS/SSL certificates and configuration in the web server will be removed in a future version. No changes to the current system have been made in 10.11, however future versions will remove the current system and instead will provide advanced instructions to configure the Kestrel webserver directly for this relatively niche usecase. We strongly advise anyone using the current TLS options to use a Reverse Proxy for TLS termination instead if at all possible, as this provides a number of benefits

Cool, thanks for the explanation.
a single application that gets bundled with all necessary dependencies including versioning
Does that mean that if I were to install Application A and Application B that both have dependency to package C version 1.2.3 I then would have package C (and all of its possible sub dependencies) twice on my disk? I don’t know how much external dependencies applications on Linux usually have but doesn’t that have the potential to waste huge amounts of disk space?
Sorry to ask, I’m not really familiar with Linux desktop nowadays: I’ve seen Flatpak and Flathub talked about a lot lately and it seems to be kinda a controversial topic. Anyone wanna fill me in what’s all the noice about? It’s some kind of cross-distro “app store” thingy?
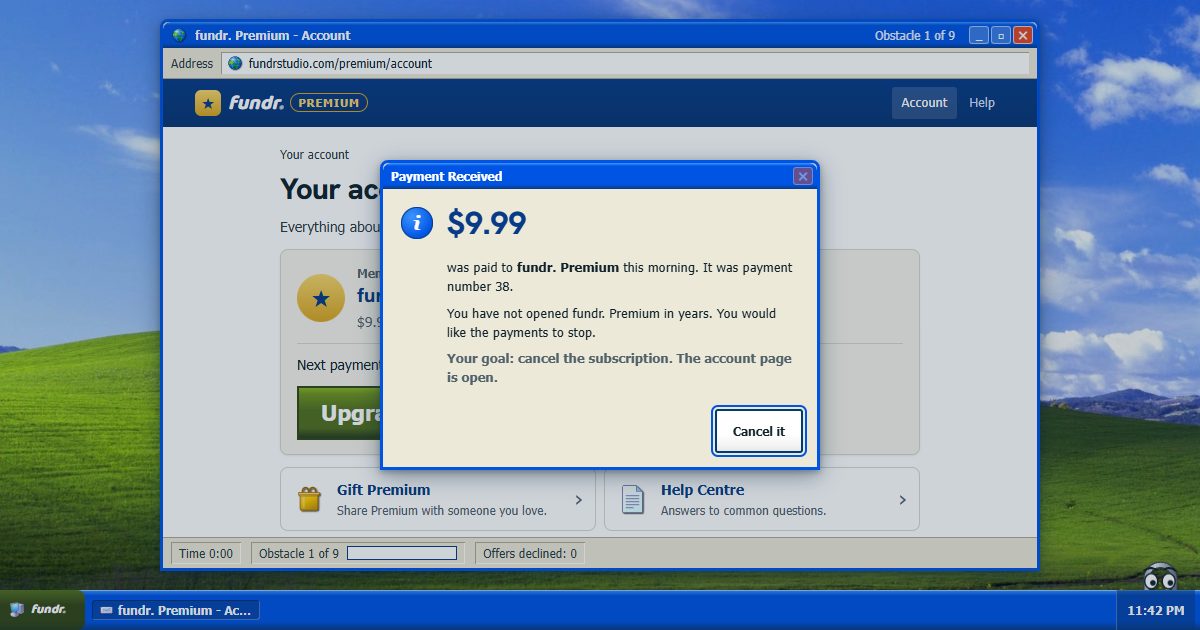
As others have mentioned, adblockers seem to break it somehow. It’s probably not intentional. The page doesn’t serve any (actual) ads, so it’s safe to try disabling your ad blocker. For me, refreshing the page a couple of times also fixed the issue even with uBO enabled.